Baidu Unlimited OCR 2: what it is and what we could test
Unlimited OCR is an open model from Baidu that turns scanned pages into text. Its selling point is that it can take the pages of a document together, in one request, so text that continues across pages stays in context. Version 2 was announced on 27 October 2026. This is mainly a source-based explainer: we did not run version 2 or install anything. We ran one small test of the earlier version on Baidu's hosted demo with a made-up notice, and we could not confirm the multi-page part ourselves.
Quick facts
- Who: Baidu. The code is at github.com/baidu/Unlimited-OCR, a repository under Baidu's GitHub organisation. The model pages sit under Baidu's verified Hugging Face organisation, and the paper (arXiv 2606.23050, 22 June 2026) lists Baidu Inc.
- Licence: the repository's LICENSE file is the MIT licence (Copyright 2026 Baidu), and the Hugging Face model pages for both versions list "license: mit" in their metadata. We did not review any other terms.
- Versions: the paper and the first model (baidu/Unlimited-OCR) date from June 2026. The README says Unlimited OCR 2 (baidu/Unlimited-OCR-2) was released on 27 October 2026. We found no separate paper for version 2; the README still points to the June paper.
- Multi-page: Baidu's README says all pages of a document are parsed in one request, with pages passed in order as images. Baidu's paper reports good results at 20 pages and, in its own tests, 40 or more pages. It also says the model cannot parse truly unlimited length, because context is finite.
- Version 2 claims: the README's "unlimited-horizon" and hundred-page benchmark claims are Baidu's own and we did not check them.
- Hardware: Baidu's README lists the setup it tested on (an NVIDIA A800 80 GB GPU, with CUDA). We found no stated minimum requirement. We did not try to run it locally.
- Free try: Baidu's Hugging Face Space runs the first version in the browser, with no sign-in needed in our test. Usage limits unverified. No payment or card was requested.
- India: we found no India-specific statement in the sources we read, and we did not verify availability for India.
Who it is useful for
Unlimited OCR is a specialised document model whose weights are public, so developers can run it on their own servers or inside other tools. Baidu describes the multi-page design as the point: the model sees the whole document at once instead of page by page. It is aimed at developers building document pipelines, not at readers who need to scan a single page.
What we tested
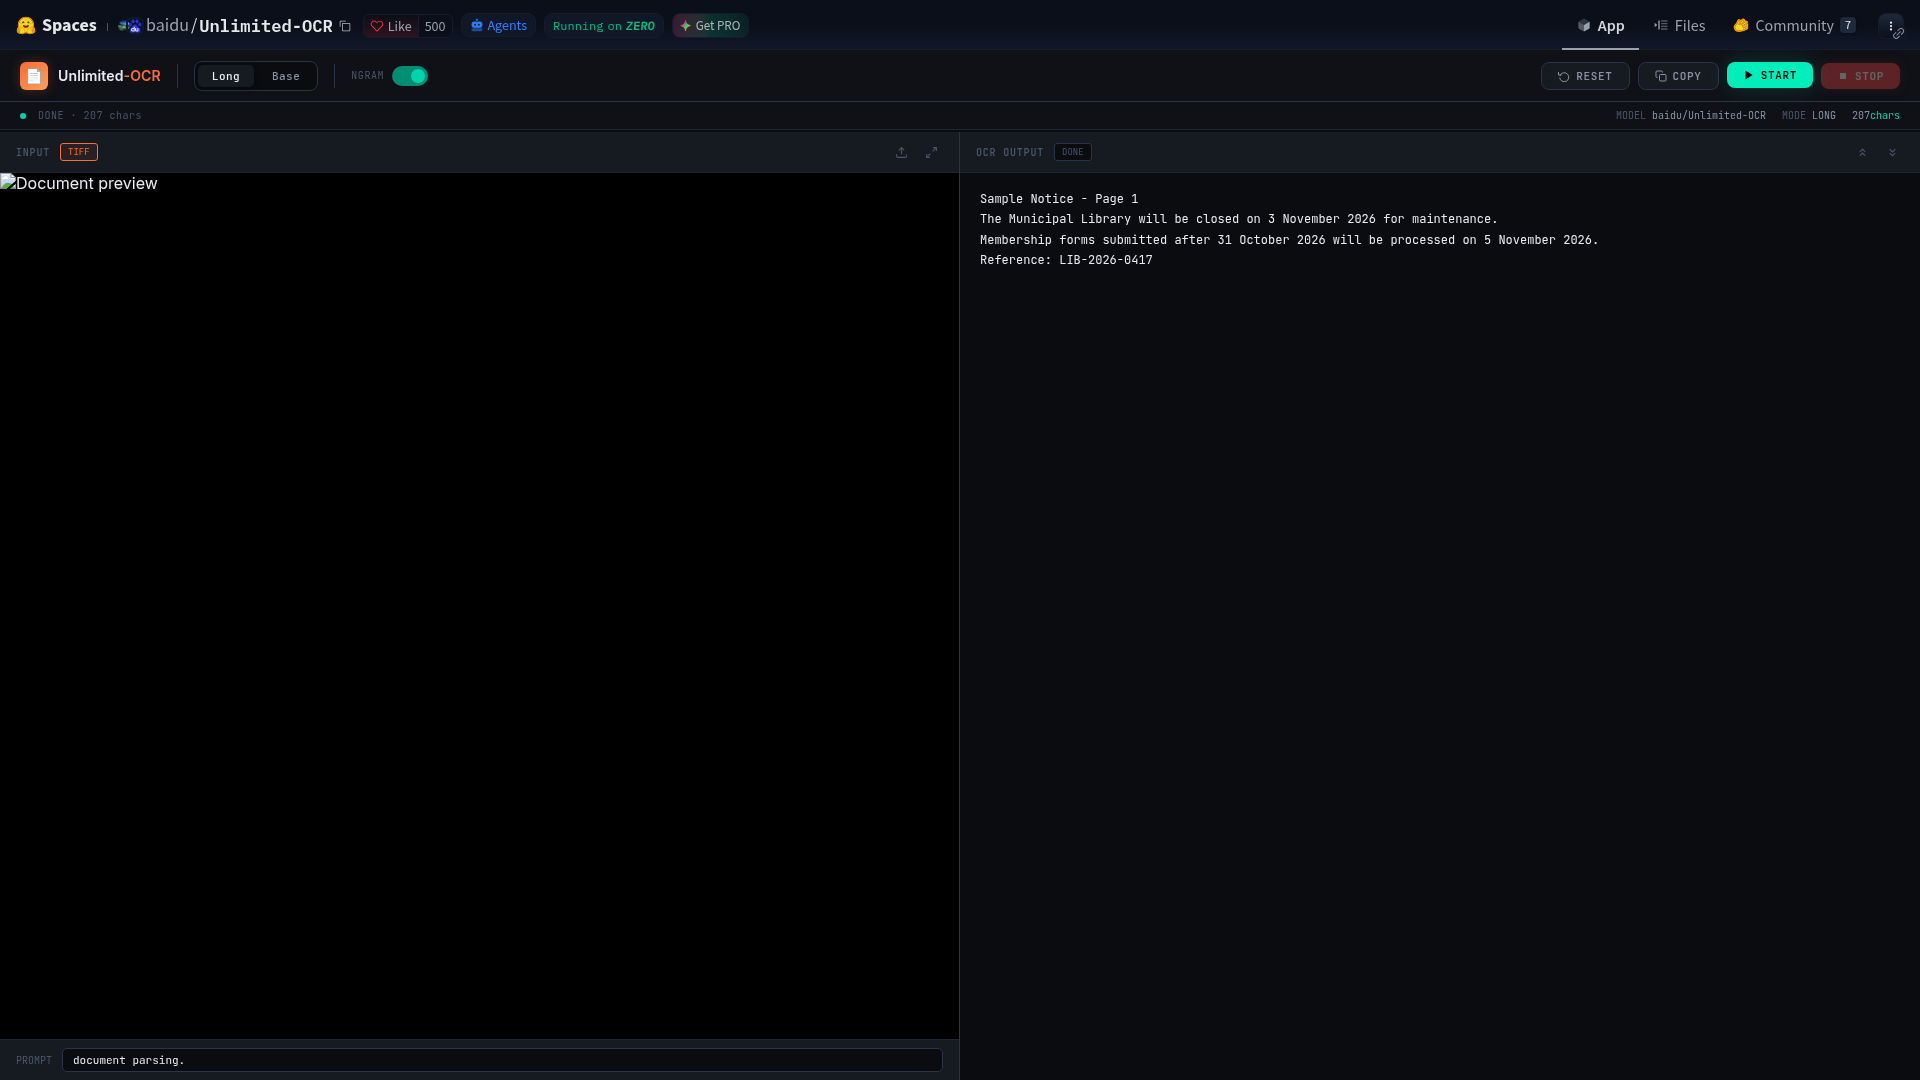
On 27 October 2026 we opened Baidu's Hugging Face Space on a desktop browser. The Space showed the model name baidu/Unlimited-OCR, which is the first version, not version 2.
- One image: we uploaded a made-up one-page library notice as a PNG and pressed Start. It finished in about 40 seconds. The text came out correct: the title, the 3 November 2026 closure date, the forms line and the reference number. The model joined wrapped lines.
- Two pages: we then uploaded a made-up two-page TIFF. The output contained only the text of page 1. We do not know whether this is a limit of the demo, of TIFF handling or of our file, so we make no claim about multi-page from this.
- PDF: a two-page PDF stayed on "Rendering PDF" in our browser and we did not get a result.
- Not tested: version 2, a local install, speed benchmarks, accuracy on real scans, other languages and Baidu's benchmark numbers.
What to take from this
- Real and from Baidu, with an MIT licence stated in the repository and on the model pages.
- Multi-page in one request is Baidu's design claim, backed by its own paper. We did not reproduce it.
- Version 2 is new today. Its extra claims are the README's only.
- Try the free demo with non-private, single-image samples. Do not upload private documents to a public demo.
Sources checked 27 October 2026. Benchmark and speed figures come from Baidu's own paper and README, not from independent tests.